Confident AI
Trace and monitor your AI SDK applications with Confident AI
Confident AI is an LLM observability and evaluation platform for teams building reliable AI applications in development and production.
confident-trace, Confident AI's OpenTelemetry-native tracing SDK, traces AI SDK applications without changing your calls — every generateText and streamText call shows up in the Observatory as a trace with agent, step, model, and tool spans, so you can see which tools your app chose, what each model call cost, and run evaluations on the result.
Confident AI integrates with the AI SDK to provide:
- Traces with the full agent, step, model, and tool hierarchy
- Token usage and cost on every model call
- Threads that group a conversation's turns into one unit
- Online evaluations that score traces as they are ingested
Setup
Tracing requires Node.js 22 or later and AI SDK >=7.0.93 <8.
Set Your API Key
Sign up or log in to Confident AI to get your project API key, then set it as an environment variable:
For users in the EU region set
CONFIDENT_OTEL_ENDPOINT="https://eu.otel.confident-ai.com/v1/traces"
Register the Telemetry Integration
The createVercelAITracer() function returns a tracer that maps AI SDK spans onto
Confident AI's span types. Pass it to OpenTelemetry and register that once at
application startup, before any AI SDK call. init() sets up the exporter that
ships the spans to your project:
In Next.js, put this in instrumentation.ts at your project root — Next.js calls
register() for you. For Node.js applications without Next.js, run the same two
lines at the top level of your entry file:
Your AI SDK calls stay exactly as they are. Every span carries the Vercel AI SDK integration label, nests under whatever span is active when the call is made, and captures:
- Agent and step spans — one span for the overall
generateTextorstreamTextcall, plus one span per step in a multi-step run. - Model calls — LLM spans with the model name, token usage, finish reason, and normalized input/output messages, including the tool calls the model requested.
- Tool calls — tool spans with the tool name, its input, and its result, nested under the step that ran them.
- Content — prompt and response text, captured by default with no size limit unless you configure one, and subject to the content policy.
Reasoning and binary content parts are marked but not exported, and raw request headers, arbitrary SDK metadata, and exception messages are left out. Embeddings, reranking, and the image and audio APIs are outside this integration's scope.
Initialize once, shut down once. In a long-running server, call init() at
startup and runtime.shutdown() during graceful shutdown, after in-flight
requests and streams finish — never per request. In a serverless function,
call runtime.flush() at the end of the handler instead, once any stream has
finished, so spans are exported before the function freezes.
Advanced Features
Online Evals
You can configure what happens to your incoming traces on Confident AI's workflows page.
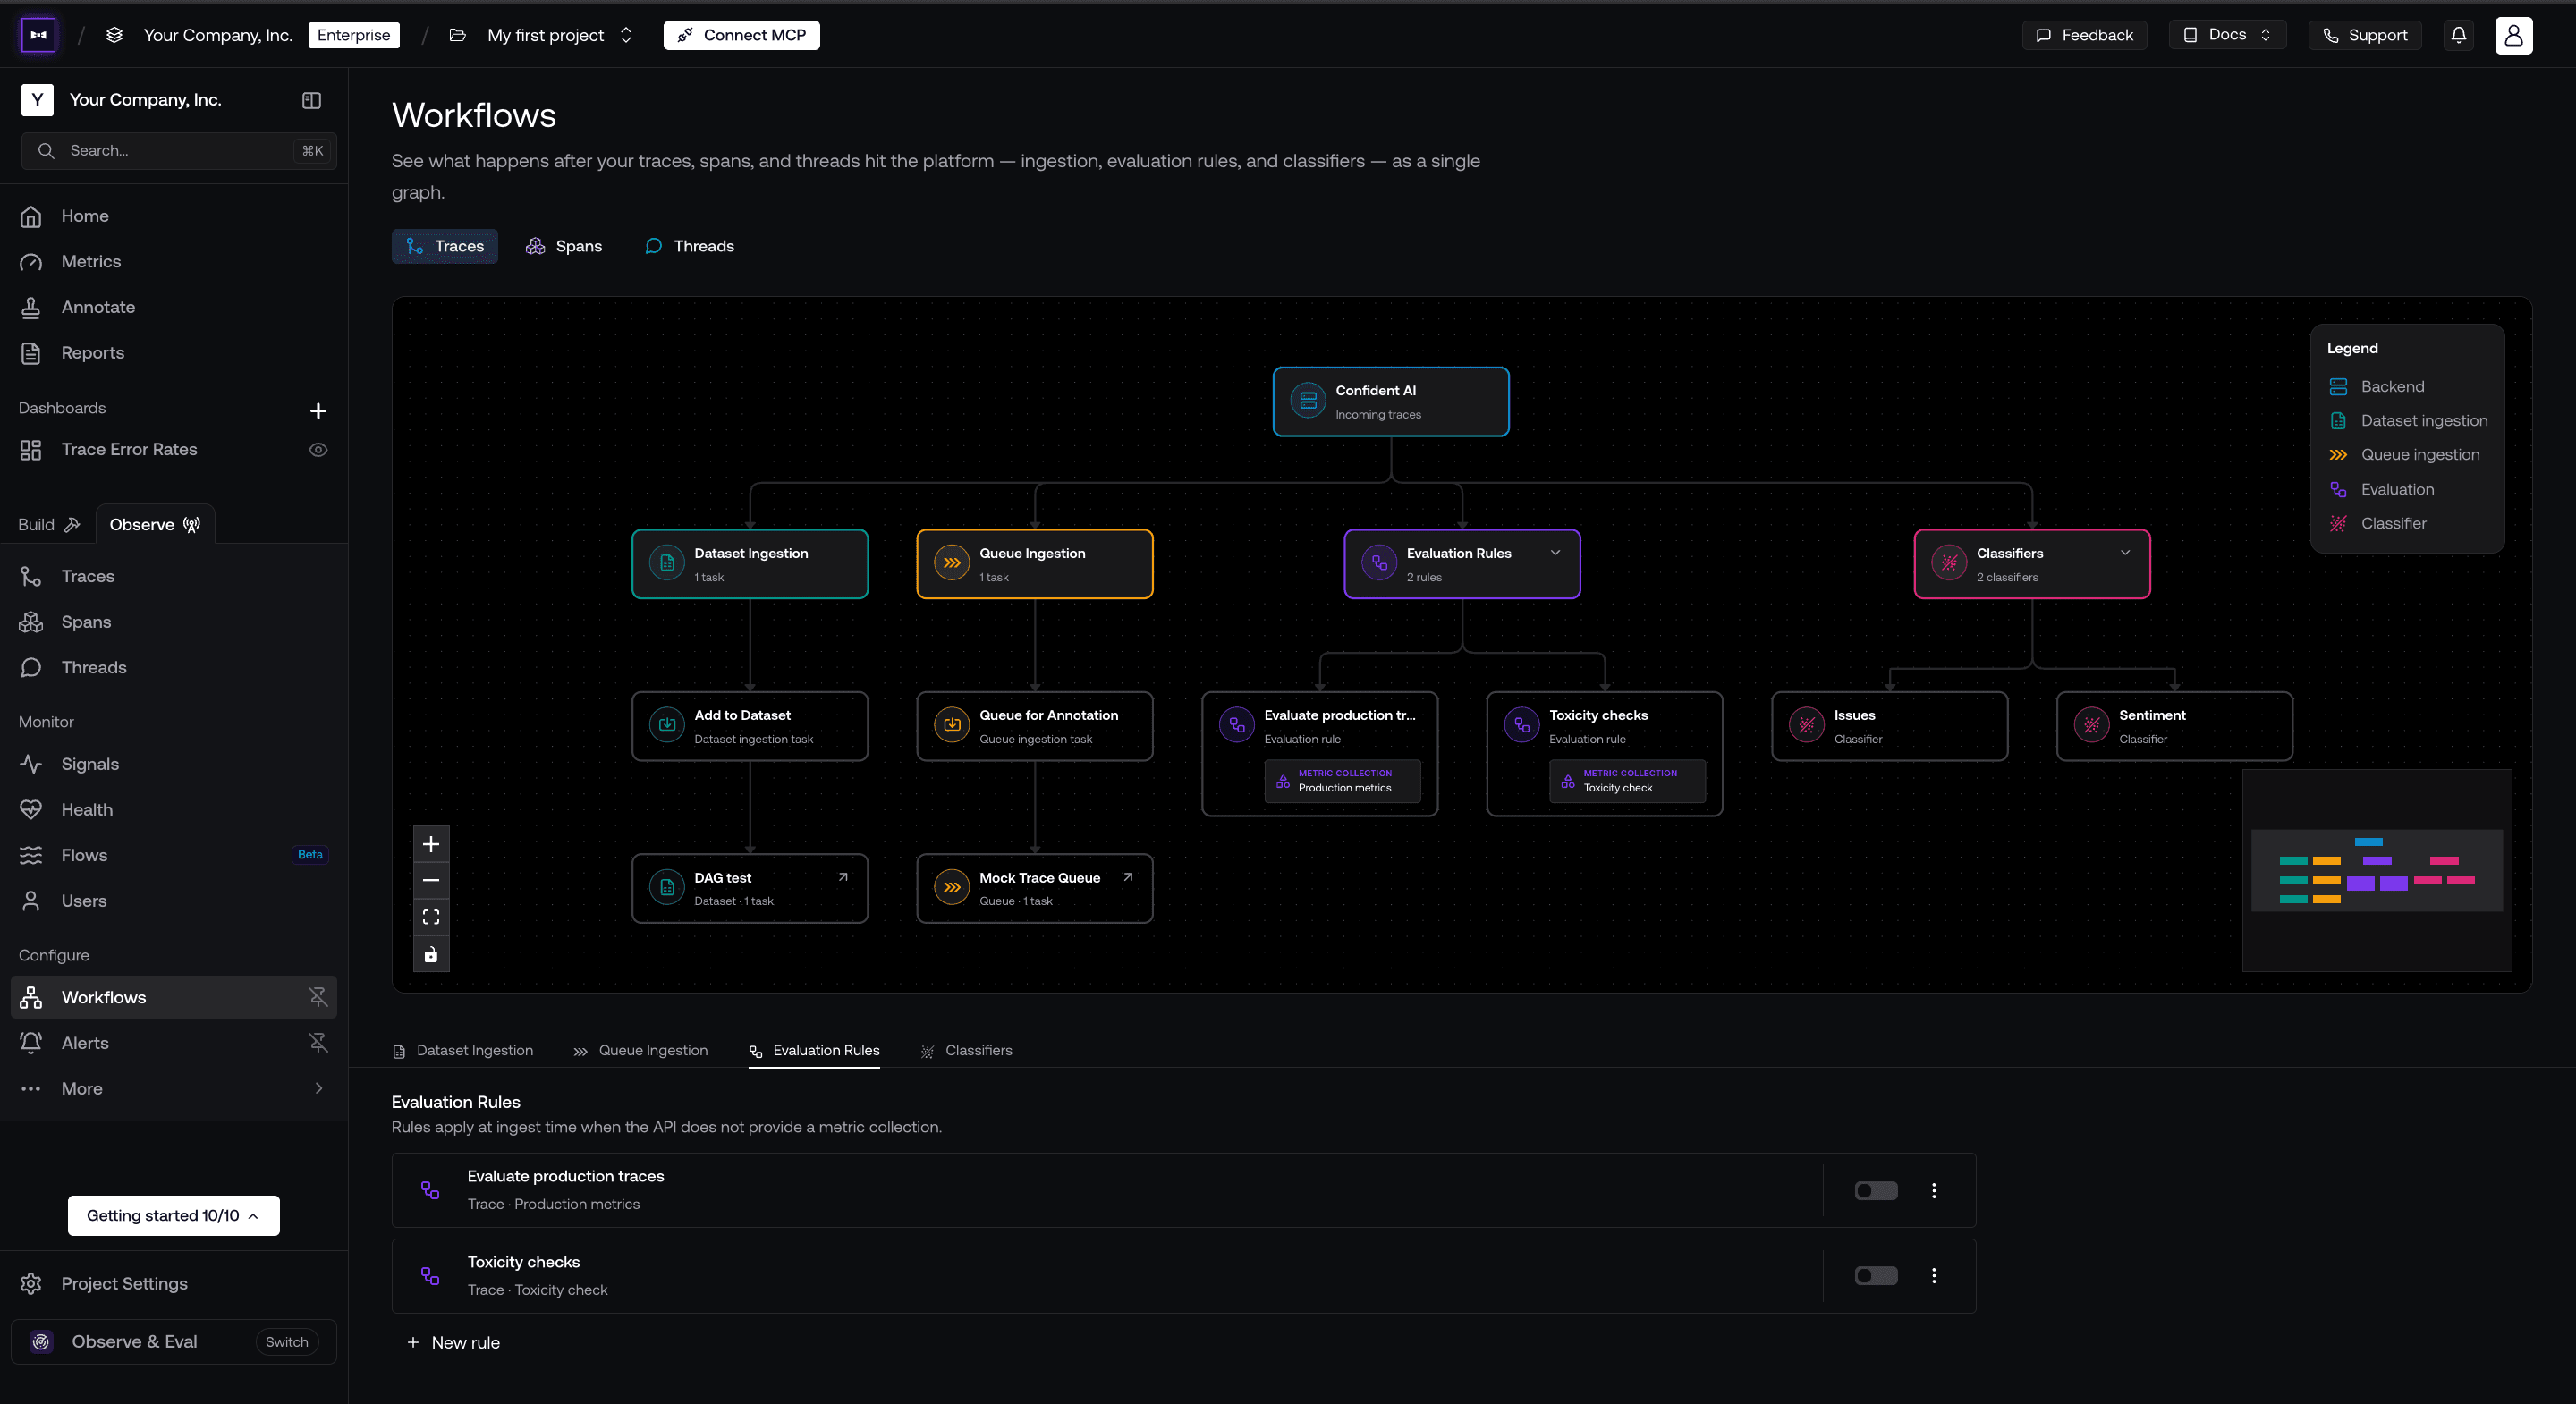
Here's the workflows you can configure:
- Evaluation rules — evaluate incoming traces against a metric collection.
- Classifiers — label your traces by issue, sentiment, or any dimension you define, which lets you group or filter them later on.
- Queue ingestion — route your production traces into annotation queues for your internal review team to annotate them by hand.
- Dataset ingestion — ingest your production traces into datasets to reuse as test cases and iterate on results to improve over time.
You can create custom workflows for different data models like traces, spans, and threads individually as per your needs.
To evaluate a component or trace manually, pass a metric collection via updateTrace — see online evaluations.
Trace Properties
Use a trace context to attach attributes you know before the call starts. It creates no extra span — the trace started by generateText() inherits everything you pass:
Group Traces Into Threads
confident-trace provides a turn() method you can use to group sequential AI SDK calls into one turn. Reuse the same thread ID on later turns to group them into one thread you can view and evaluate on Confident AI:
Troubleshooting
- No traces at all: confirm
registerTelemetry()runs before the first AI SDK call. In Next.js, that meansinstrumentation.tsat the project root, not inside a route. Registering no telemetry integration disables AI SDK telemetry entirely. - Traces stop partway through a run: the process exited before the export queue drained. Call
runtime.shutdown()at exit, orruntime.flush()at the end of a serverless handler. - Streamed calls arrive incomplete: finish consuming or abort the stream before flushing or shutting down.
- Traces are missing content: check AI SDK's
recordInputsandrecordOutputs, andcaptureContentoninit().
For anything else, see Confident AI's troubleshooting guide.